Knowledge Graph Data structure#
Iggytop is built on top of BioCypher by providing a set of adapters as well as an ontology to generate knowledge graphs for TCR-epitope datasets.
Data Generation Process#
The generation process relies on the create_knowledge_graph.py script. The pipeline follows these key steps:
1. Source Data Harmonization#
Similar to the tabular data structure, IggyTop leverages BioCypher adapters to read and harmonize data:
Mapping: Source formats are mapped to internal registry keys.
Gene Normalization: V(D)J genes are aligned with IMGT standards.
Sequence Processing: Harmonization of CDR3 and epitope sequences.
The harmonization is based on tidytcells wherever possible and tries to follow AIRR and IMGT standards.
2. Graph Construction#
Instead of just stacking tables, the pipeline uses the BioCypher framework to:
Instantiate Nodes based on the Ontology.
Create Edges representing the associations between Nodes.
The resulting graph can be exported to various formats (Neo4j, NetworkX, GraphML).
3. Processing Options#
Graph construction#
Users can customize the graph generation using several flags in create_knowledge_graph.py:
Receptor Types: Specify which receptors to include (e.g.,
--receptors TCR BCR).Adapter Selection: Choose specific databases to include in the graph.
10X Data Filtering: To address concerns regarding the confidence of some large-scale datasets, users can use the
--filter-10xflag to exclude data originating from the 10X Genomics dataset. This will remove records stored in the source databases which stem from this dataset. This flag is also set for the released dataset (deduplicated_anndata.h5ad)Note The ITRAP dataset contains data from this dataset. The ITRAP data are the (5k out of 60k) pairs that have passed the ITRAP qc filtering and are therefore considered high quality. These records are not filtered out. If you want to completely exclude 10X data, consider excluding ITRAP from the pipeline.
Graph queries#
Follow the instructions in the readme to start the docker container running a neo4j instance with the full knowledge graph. The knowledge graph can then be explored using Neo4j and Cypher see here for more information on how to use Neo4j.
Knowledge Graph#
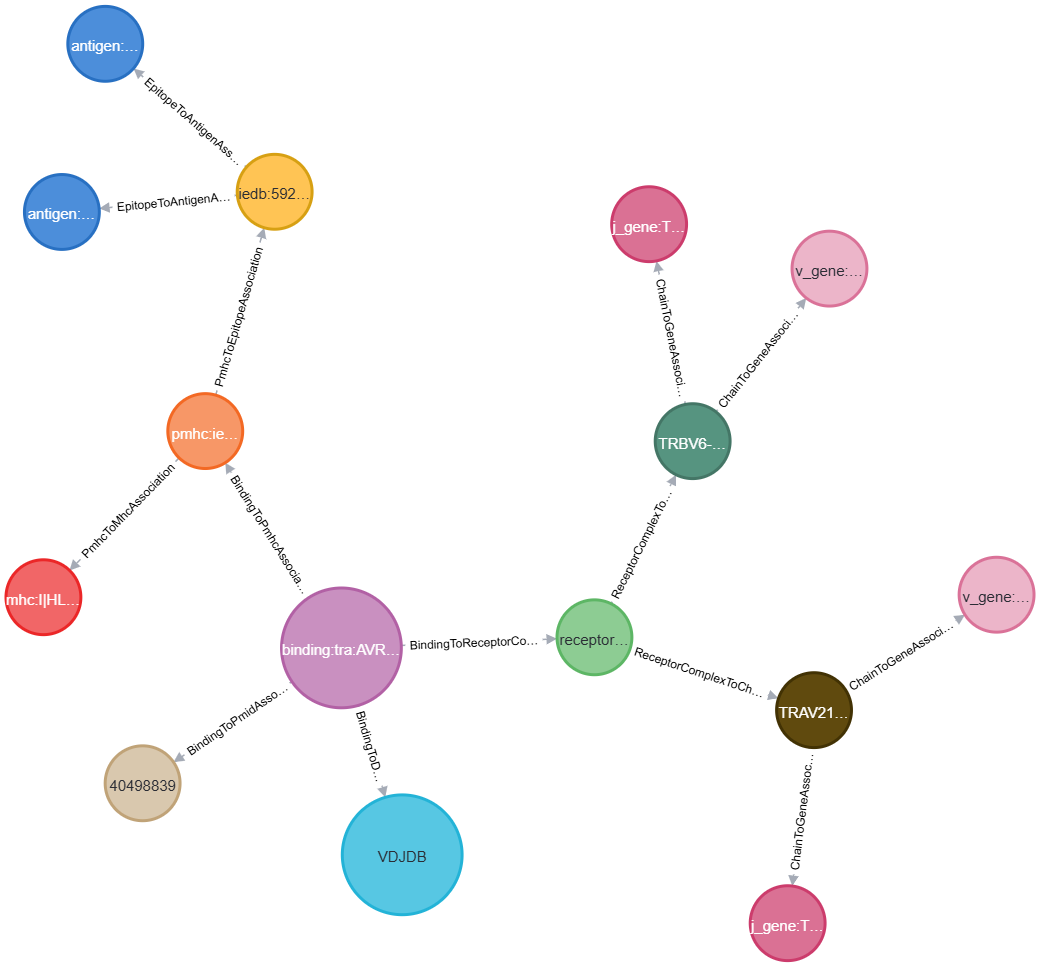
Design Choices#
Ontology#
BioCypher uses the Biolink ontology and allows custom modifications. This is done using configuration files.
The ontology used for iggytop is defined in config/schema_config.yaml. This includes defining the node and edge types and their relationships (hierarchy).
entity
├── association
│   ├── binding to database association
│   ├── binding to pmhc association
│   ├── binding to pmid association
│   ├── binding to receptor complex association
│   ├── chain to gene association
│   ├── epitope to antigen association
│   ├── pmhc to epitope association
│   ├── pmhc to mhc association
│   └── receptor complex to chain association
└── named thing
    ├── PMID
    ├── binding
    ├── biological entity
    │   ├── antigen
    │   ├── gene
    │   │   └── immune receptor gene
    │   │       ├── j_gene
    │   │       └── v_gene
    │   ├── pmhc
    │   ├── polypeptide
    │   │   ├── epitope
    │   │   ├── immune receptor chain
    │   │   │   ├── chain_1
    │   │   │   └── chain_2
    │   │   └── mhc
    │   └── receptor complex
    └── database

INFO:biocypher:
entity
├── association
│   ├── binding to database association
│   ├── binding to pmhc association
│   ├── binding to pmid association
│   ├── binding to receptor complex association
│   ├── chain to gene association
│   ├── epitope to antigen association
│   ├── pmhc to epitope association
│   ├── pmhc to mhc association
│   └── receptor complex to chain association
└── named thing
    ├── PMID
    ├── binding
    ├── biological entity
    │   ├── antigen
    │   ├── gene
    │   │   └── immune receptor gene
    │   │       ├── j_gene
    │   │       └── v_gene
    │   ├── pmhc
    │   ├── polypeptide
    │   │   ├── epitope
    │   │   ├── immune receptor chain
    │   │   │   ├── chain_1
    │   │   │   └── chain_2
    │   │   └── mhc
    │   └── receptor complex
    └── database
Node and Edge Types#
The graph is organized as a hub-and-spoke hierarchy around a central binding node, which represents one reported TCR/BCR-epitope pairing:
Each
bindingnode has exactly one edge to areceptor complexnode and exactly one edge to apmhcnode — together these identify which receptor was reported to recognize which peptide-MHC.The same pairing reported by several sources (e.g. the same complex-pmhc pairing appearing in both VDJDB and IEDB, or the same source citing multiple publications) collapses onto the same
bindingnode: its ID is built from the receptor complex and pmhc content, deliberately excluding source/database/PMID. That shared node can then carry edges out to everydatabaseandPMIDnode that reported it, rather than one row per source.receptor complexandpmhcare themselves join nodes: areceptor complexlinks to itschain_1/chain_2nodes, and apmhclinks to itsepitopeandmhcnodes. Because these nodes are shared (deduplicated) rather than duplicated per record, records with, e.g., the same V/J gene or the same epitope naturally converge on the same downstream nodes — this is how the graph surfaces similarities between receptors and epitopes across the whole dataset, rather than just stacking independent rows.
Nodes#
Node |
Parent type |
Key properties |
|---|---|---|
|
named thing |
|
|
biological entity |
|
|
immune receptor chain → polypeptide |
|
|
immune receptor gene → gene |
— (id-only reference nodes) |
|
biological entity |
|
|
polypeptide |
|
|
biological entity |
|
|
polypeptide |
|
|
named thing |
|
|
named thing |
|
Edges#
Edge |
Subject → Object |
|---|---|
binding to receptor complex association |
|
binding to pmhc association |
|
binding to database association |
|
binding to pmid association |
|
receptor complex to chain association |
|
chain to gene association |
|
pmhc to epitope association |
|
pmhc to mhc association |
|
epitope to antigen association |
|
See config/schema_config.yaml for the full property/type definitions and the ontoweaver_mapping_*.yaml files (and ontoweaver_transformers.py) for exactly how each node’s ID and properties are built from the source table columns.
Output Formats and Availability#
The knowledge graph can be exported in several ways:
Neo4j: Optimized for graph database queries. Check out the Docker guide in the README.
NetworkX / GraphML: Useful for Python-based graph analysis and visualization in tools like Cytoscape.
AIRR JSON: While natively a graph, output can be converted back to the AIRR format (tabular).
Bimonthly Releases#
Knowledge graph exports as knowledge_graph.tar.gz are provided in bimonthly releases.
Creating Your Own Graph#
You can run the graph generation locally to create custom subsets or use specific versions of the data:
python create_knowledge_graph.py --adapters VDJDB MCPAS --output-format networkx
Note that some parameters are defined in the config/biocypher_config.yaml. Check out this file and change it for more control (eg defining output type).